
What Are Local LLMs?
Cloud models are rented. You send text, get text back, and pay by the token. Local models are owned. You download the weights once, and every prompt after costs electricity. That’s it.
That’s what sets the strategy. A rented model pushes you toward shorter prompts and fewer passes. An owned model makes ten passes affordable, and the tenth one is where the quality comes from.
Why Local Models Became Usable in 2026
Two years ago, running a capable model locally meant a steep quality drop. A 7B model could write a decent email and little else, and a 70B model needed a workstation.
Three changes closed most of that gap. Quantization now shrinks a model to four bits per weight with a small quality cost. Apple Silicon ships unified memory large enough to hold a 32B model inside a laptop. And open-weight releases from Meta, Alibaba, Google, Mistral, and DeepSeek now land months, not years, behind the closed models they chase.
The Stanford AI Index has tracked that distance every year since 2023. The trend has held through each release cycle. The best open-weight model sits closer to the best closed one than it did the year before. The 2026 AI Index reports the same narrowing.
We ask a narrower question. Can a 32B model turn a brief into a draft that needs an hour of editing instead of a rewrite? On that test, the answer flipped in the last twelve months.
What a Local-First Content Pipeline Looks Like
Small models handle structured jobs. Larger models handle generation. Local inference has no meter, so you can run every stage on every piece. That’s the whole design.
| Pipeline stage | Local model role | Model size | Why local wins here |
|---|---|---|---|
| Research and briefing | Summarize sources, extract quotes, draft the brief | 7B to 13B | Proprietary research never leaves the machine |
| First draft | Article drafts, social variants, email copy | 13B to 32B | No per-generation cost, so you iterate freely |
| Editorial review | Grammar, voice compliance, banned-word and slop scans | 7B to 13B | Sub-second responses across an entire library |
| SEO and metadata | Meta descriptions, OG tags, schema, alt text | 3B to 7B | Batch hundreds of posts in one pass |
| Distribution | Social variants, newsletter excerpts, repurposing | 7B to 13B | Run against the whole catalog without a budget |
The tools have settled. Ollama pulls and serves models with one command and exposes an OpenAI-compatible API, so any client library you already use works without changes. LM Studio gives you a desktop interface for testing. llama.cpp handles inference underneath both, which is why the same model runs on a Mac, a Linux box, and a gaming GPU.
Which Models to Actually Run
Model choice matters less than memory. We pick the largest model that fits, then match the family to the job. These six cover a full content pipeline without a single cloud call.
| Model family | Params | Memory at 4-bit | Best content job |
|---|---|---|---|
| Llama 3.3 | 70B | ~40GB | Long-form drafts on a 64GB or larger machine |
| Qwen 2.5 | 32B | ~20GB | Structured output: briefs, outlines, clean JSON |
| Gemma 3 | 27B | ~17GB | Line editing and voice matching |
| Mistral Small | 24B | ~14GB | Fast classification: slop scans, tagging, routing |
| Phi-4 | 14B | ~9GB | Metadata, meta descriptions, alt text, summaries |
| Llama 3.2 | 3B | ~2GB | Bulk jobs across a 160-post library |
Why Data Sovereignty Changes Content Strategy
The privacy case is simple: your data never leaves your machine. The strategic part is less obvious, and it’s the part that changes behavior.
When you use cloud APIs, every prompt passes through a third-party server. For a marketing team, that means positioning documents, competitive teardowns, customer call transcripts, and unreleased launch plans all get processed on infrastructure you don’t control. Most vendors promise they won’t train on your data. None of them can promise your data was never stored.
Local models remove the question. That changes what you’re willing to feed them.
What You Actually Need (and What You Don’t)
Hardware advice here is usually vague or overspecced. The real constraint is unified memory, because the model and its context have to fit.
| Use case | Hardware | Model size | Approx. US list price |
|---|---|---|---|
| Metadata, summaries, simple rewrites | MacBook Air M4, 24GB | 3B to 7B | about $1,300 |
| Full article drafts, social, email | MacBook Pro M4 Pro, 48GB | 13B to 32B | about $2,800 |
| Heavy creative, multi-model orchestration | Mac Studio M3 Ultra, 96GB or more | 32B to 70B | about $4,000 and up |
Prices are current US list at the time of writing. Check Apple’s configuration page before you budget; memory upgrades move that number most.
A team producing 100 pieces a month can put most of its AI workload on one 48GB laptop. We’d still rent a frontier model for the edge cases below.
The Break-Even Math Behind the $0.00
Most local-LLM cost comparisons we read stop at the electricity bill. That’s why teams buy the hardware, run twelve prompts, and go back to the API. The honest version puts the machine on the ledger.
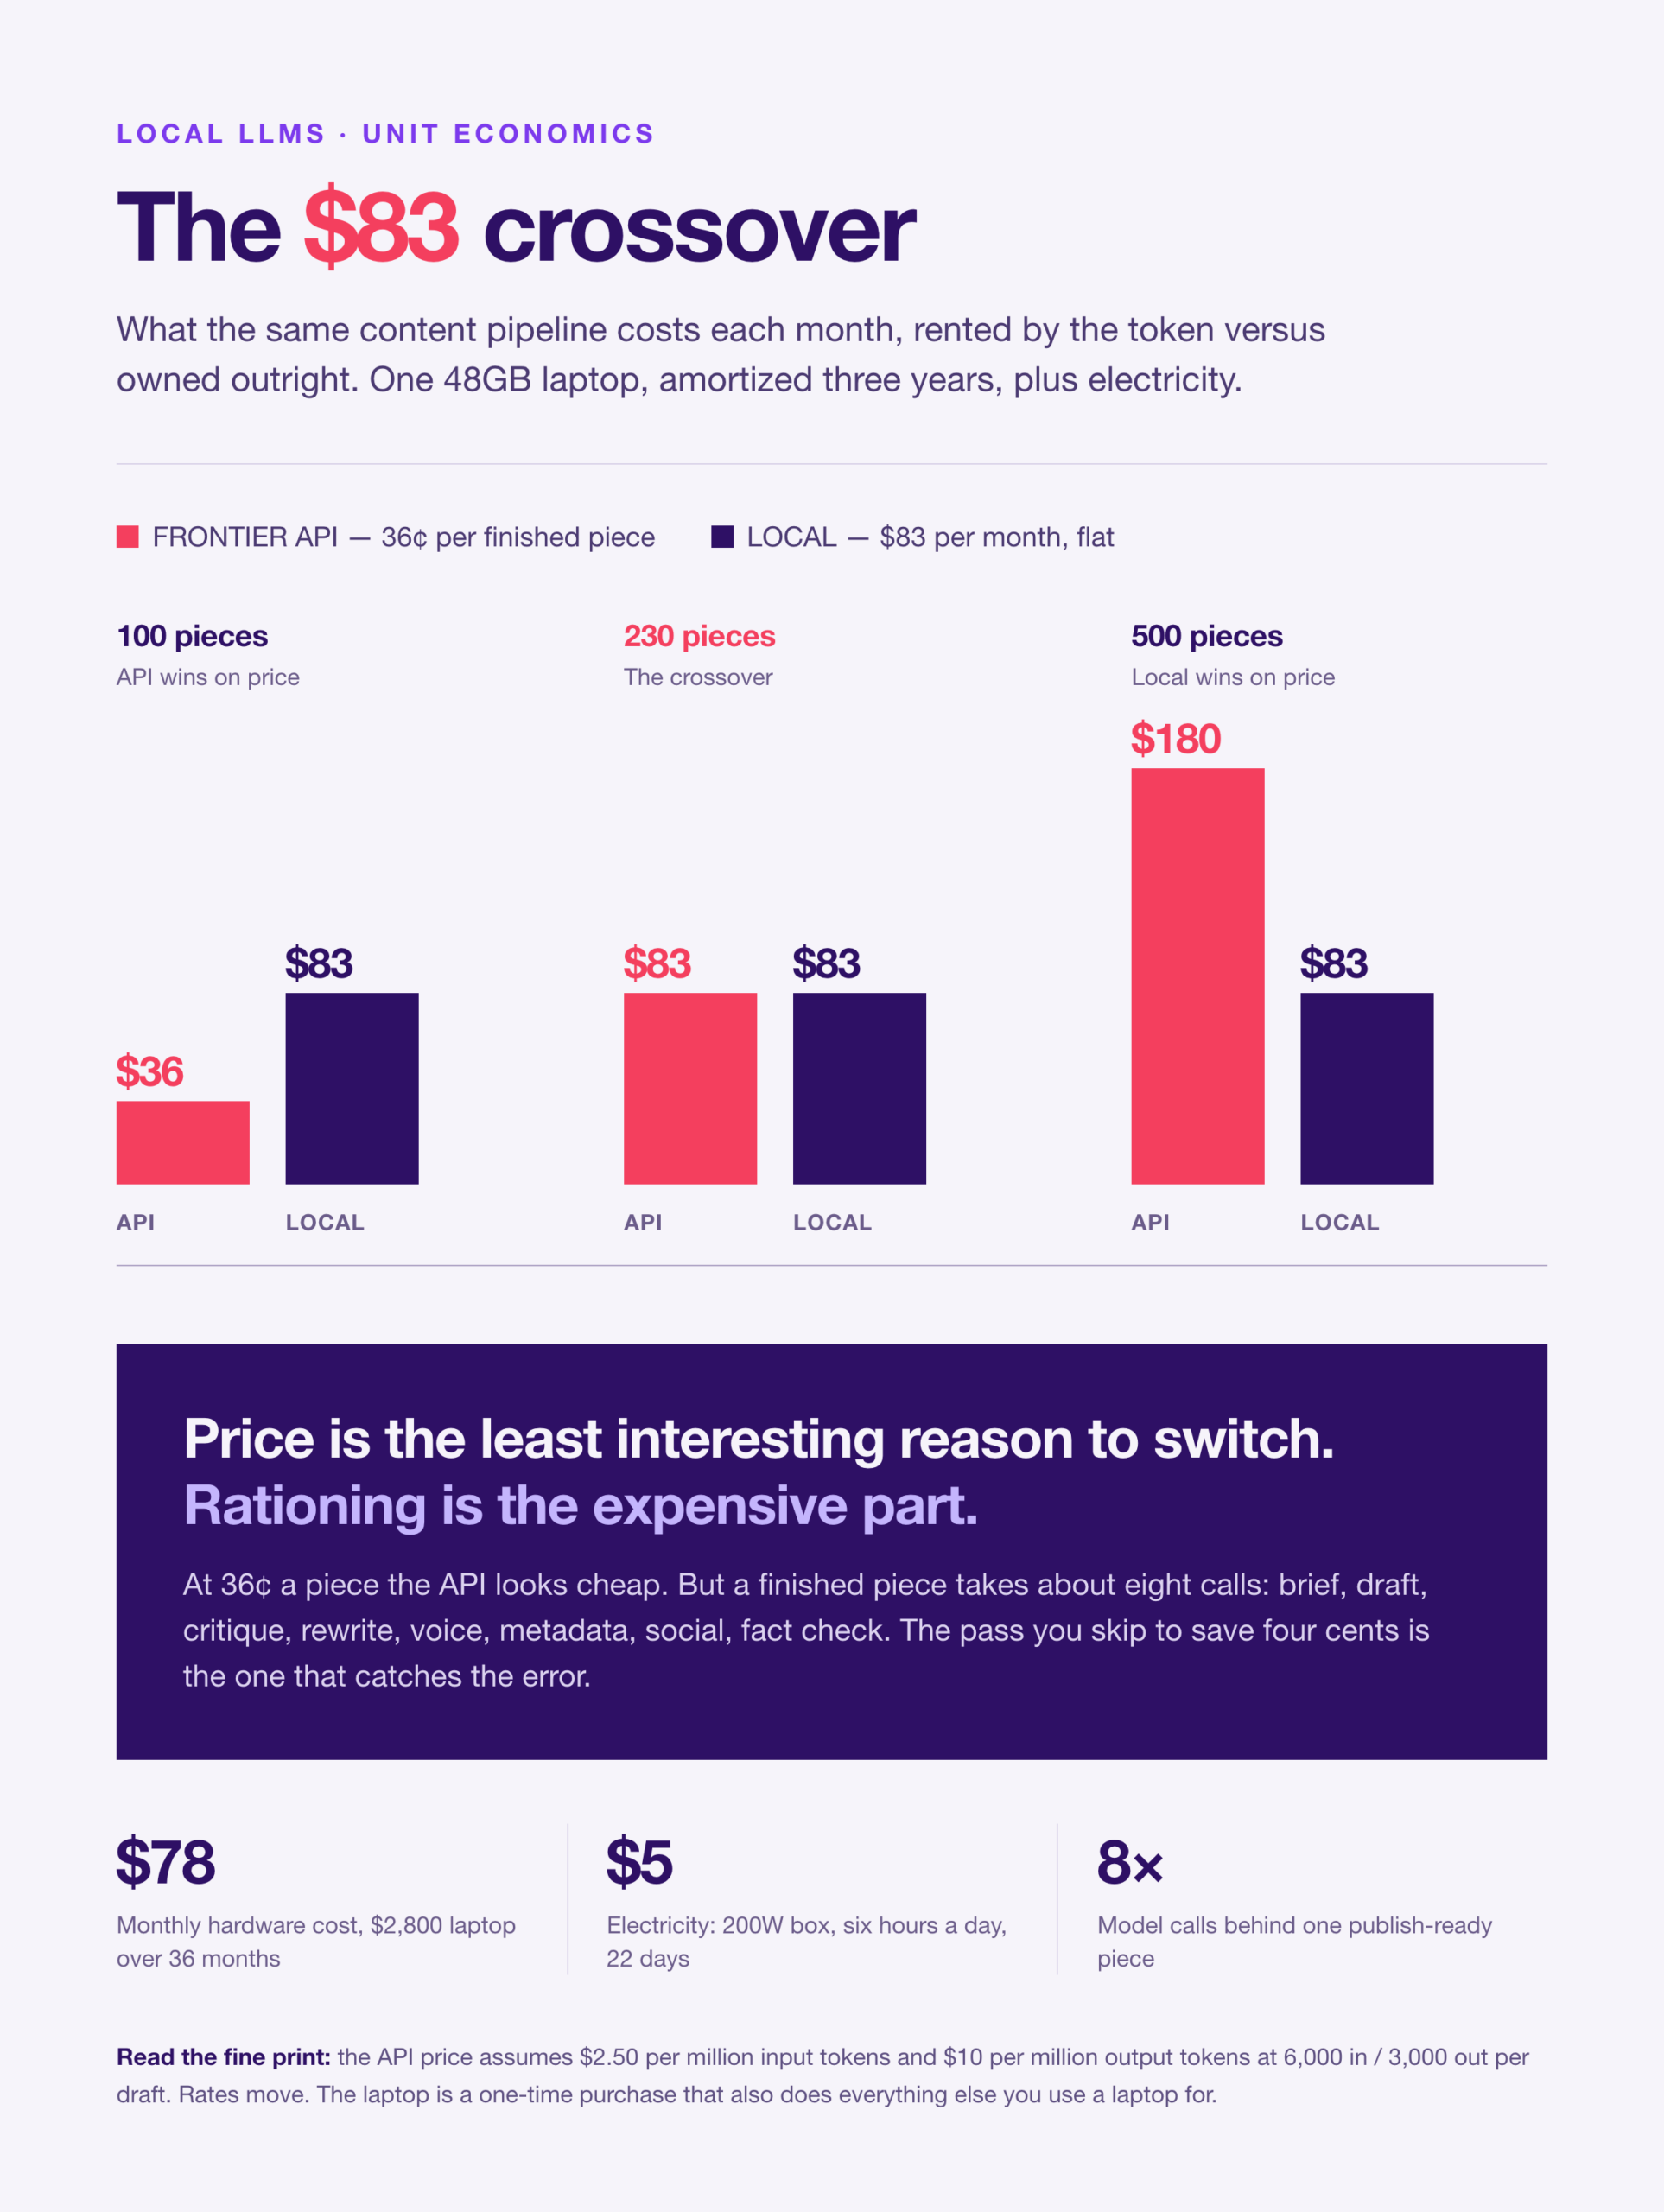
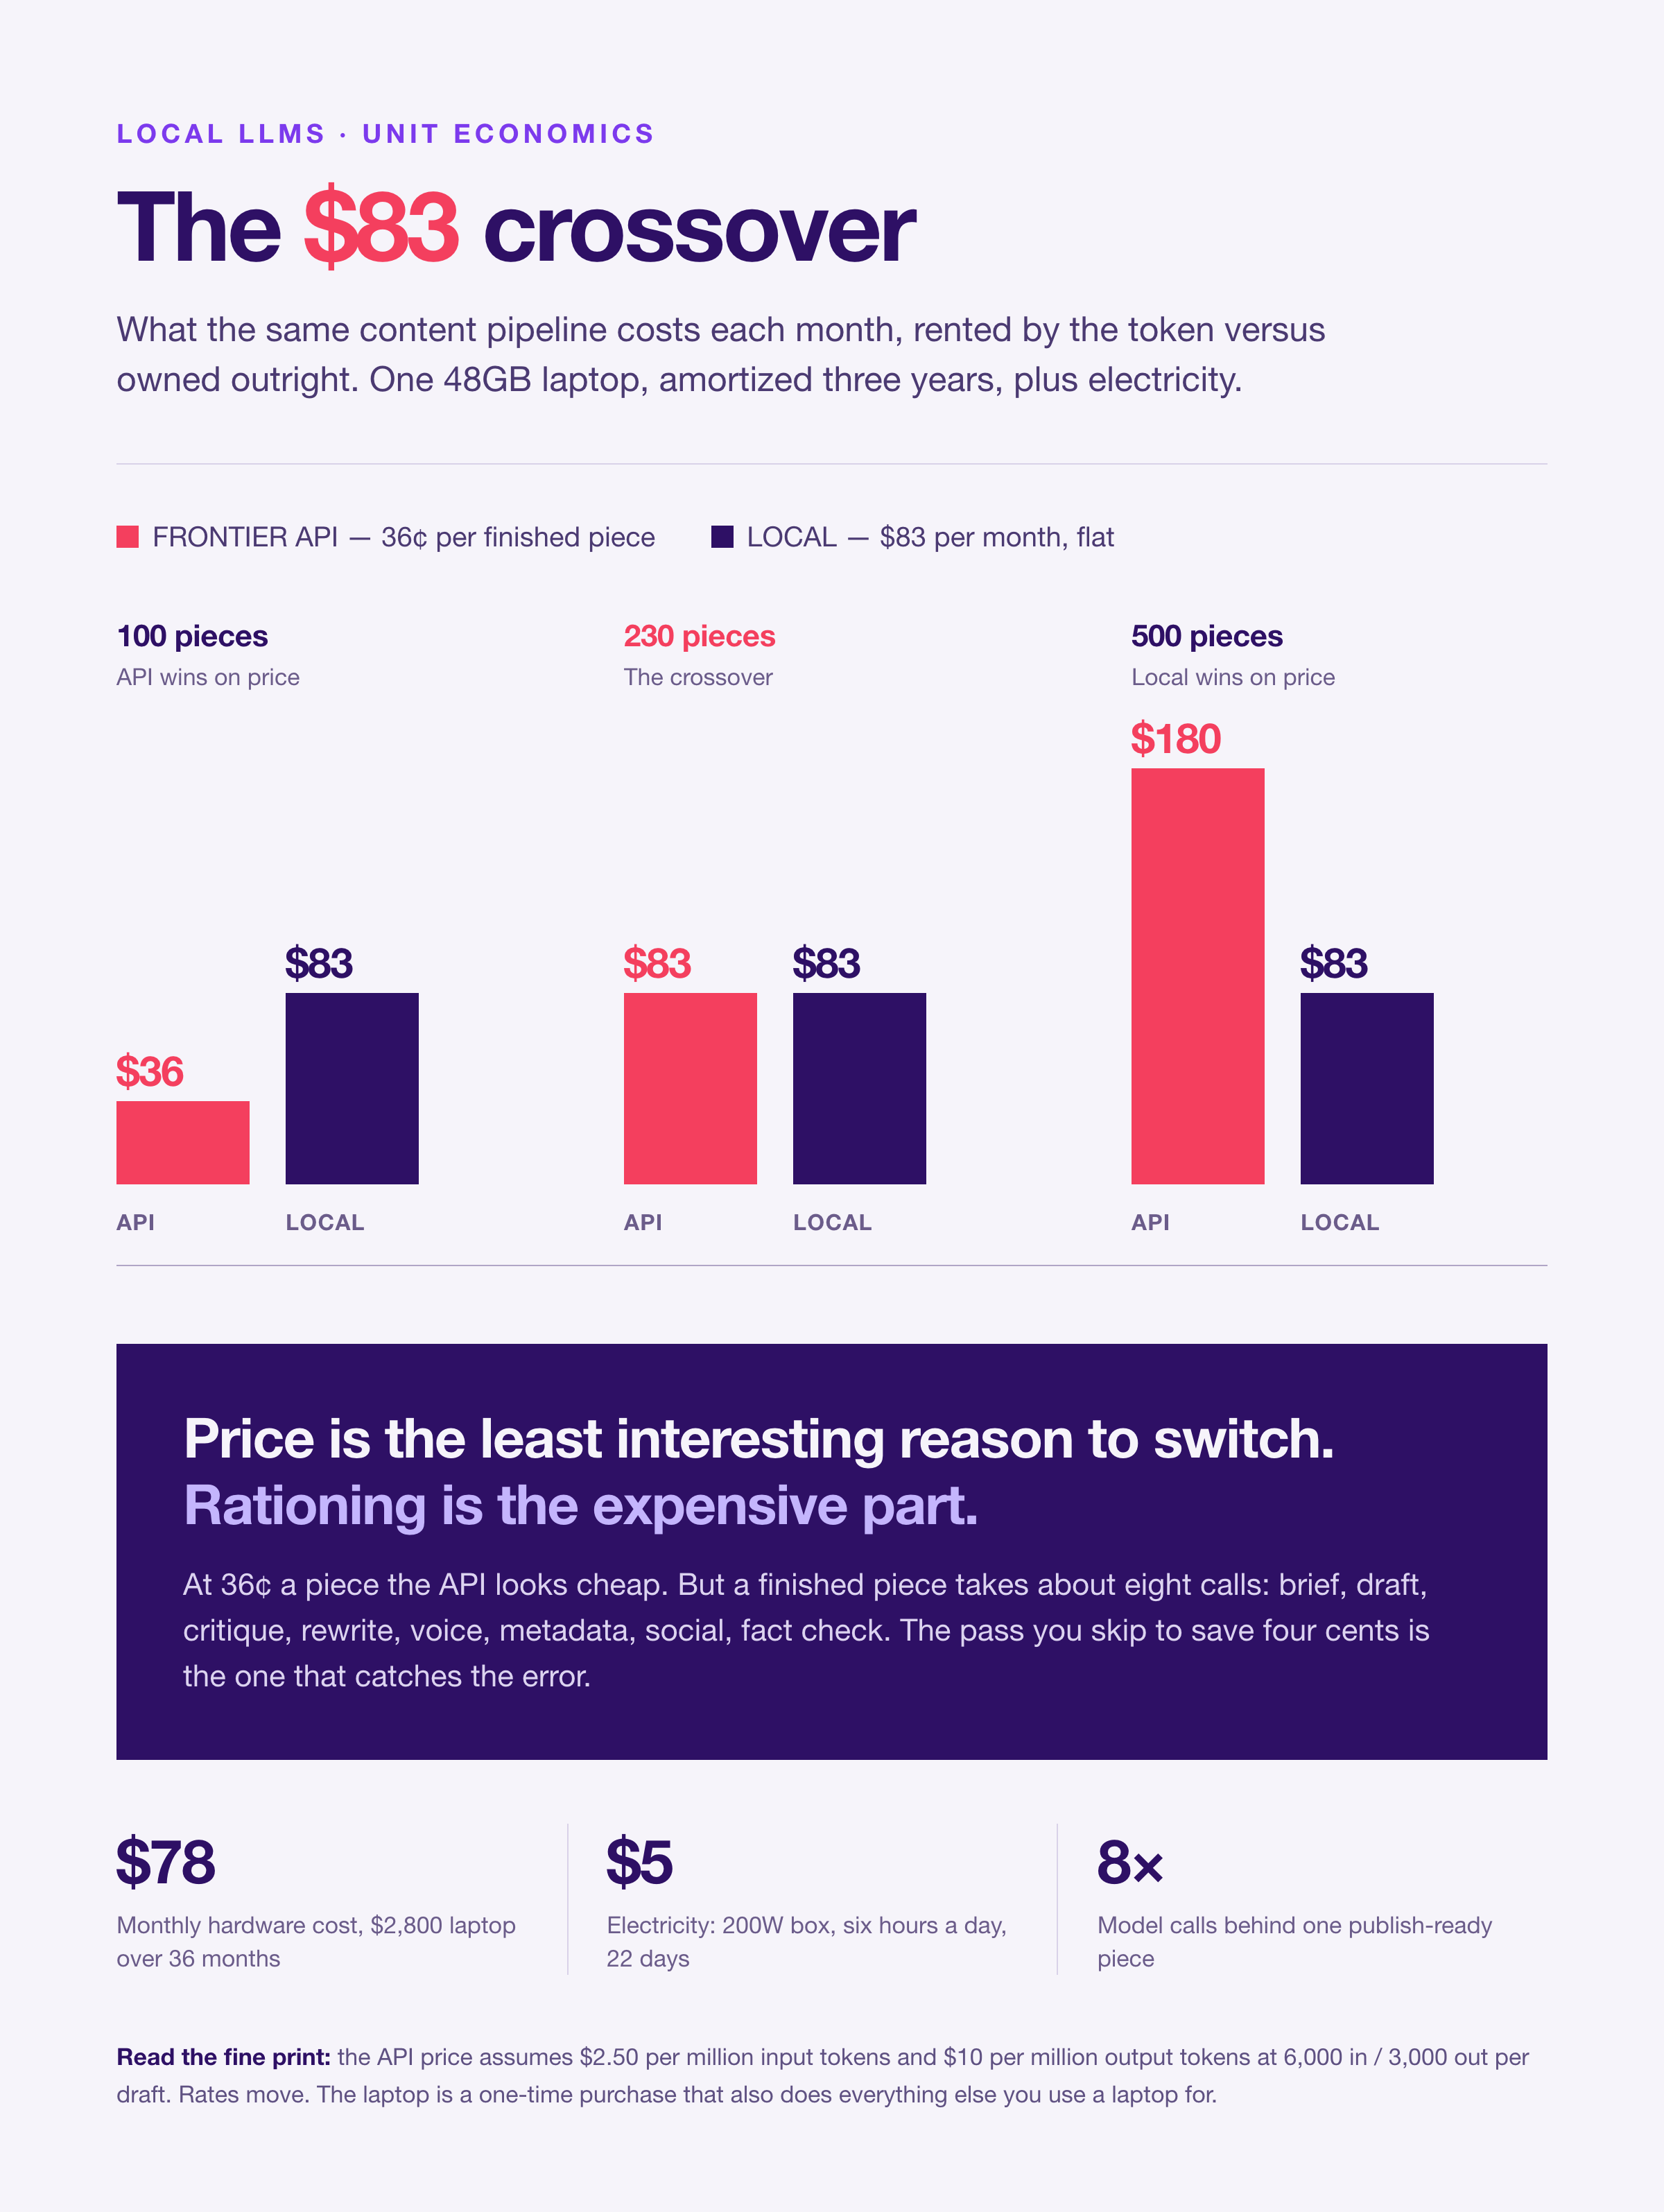
Take a $2,800 laptop amortized over three years: about $78 a month. Add $5 of electricity. Call it $83, fully loaded.
Now price the same work on a frontier API. A 2,000-word draft with a full brief in context runs roughly 6,000 input tokens and 3,000 output tokens. At about $2.50 per million input tokens and $10 per million output, that’s roughly 4.5 cents a draft. Check current rates on your provider’s pricing page; they move.
Divide $83 by 4.5 cents and you’ll land near 1,800 drafts a month.
That number flips once you count passes. A finished piece in a real editorial pipeline goes through about eight model calls: brief, draft, structural critique, rewrite, voice match, metadata, social variants, and a fact check. At 4.5 cents a call, that’s about 36 cents per piece on the API.
Now the crossover sits near 230 pieces a month. Add one full-library pass, say 160 posts through six checks each, and you’re running close to a thousand calls for a project that would normally get gated behind a budget conversation.
That’s the actual argument. Local inference doesn’t win on the price of a draft. It wins by removing the reason to ration prompts, which is how you end up running the critic pass you’d otherwise skip.
A Four-Week Rollout That Keeps Publishing
The failure mode we see is a two-week infrastructure project that ships no content. Do this instead and you’ll keep publishing the whole time.
Where Local Models Still Lose
Four jobs still belong on a frontier model in 2026.
Long-context reasoning. Feeding a 120-page earnings deck or a full book manuscript into a 32B model degrades fast. Context windows are bigger than they used to be, but quality at the far end is where the gap is widest. That’s where we still rent.
Multi-step tool use. Agentic workflows that chain search, browsing, and code execution still fail more often on small local models. The compounding error rate over six steps is the problem, not any single step.
Zero-tolerance accuracy. Pricing pages, legal disclosures, and anything a regulator might read. Run those through the best available model and a human, not a 24B model on a laptop.
The hardest creative briefs. When the assignment is a genuinely new argument rather than a competent rewrite, frontier models still produce the sharper first draft. Use local for the ten passes that shape it afterward.
From Content Velocity to Pipeline Velocity
Content output isn’t the metric. Pipeline influence is. Local inference shortens the path in three places.
More experiments per month. When a generation costs nothing, you test four messaging angles instead of one.
More surface area. A team that could sustain two posts a week sustains five. Each post is another entry point into the funnel.
Lower quality variance. Every piece runs through the same review, so the worst piece gets closer to the best one. Consistent quality converts more reliably than occasional brilliance, because buyers can’t schedule around brilliance.
Four layers of quality control that cost nothing per run change what a five-person team can ship in a quarter. That’s a capacity decision, not a tooling one.
If the budget conversation is the real blocker, bring your CFO the cost per published asset and the cycle time behind it. Our breakdown of how to prove content ROI to a CFO covers the framing that survives a finance review. Teams building the operating model around this should also read the content engineer role and the feedback loop that keeps the system honest. If model churn worries you, model-agnostic operations is the hedge: own the workflow, rent the model.
The market data points the same direction. HubSpot’s State of Marketing keeps finding that most marketers use AI while a small minority report meaningful ROI. Content Marketing Institute research shows volume expectations rising while team sizes stay flat. Inference economics sit directly between those two facts.
Local LLMs for Content Marketing: Questions
What is a local LLM?
A local LLM is a model that runs on hardware you own instead of a provider’s servers. You download the weights once and serve them with Ollama or llama.cpp, so prompts and outputs never leave your machine.
Can a local LLM replace ChatGPT for content marketing?
For most production work, yes: briefs, drafts, rewrites, metadata, and quality scans. It doesn’t replace a frontier model for long-context analysis, agentic work, or the hardest creative assignments. Run local for volume, cloud for edge cases.
How much RAM do I need to run a local LLM?
Eight gigabytes runs a 3B to 7B model, which is enough for metadata and summaries. Twenty-four gigabytes handles 13B. Forty-eight gigabytes comfortably runs a 32B model at 4-bit quantization, which is the practical sweet spot for article drafts.
Are local LLMs safe for confidential content?
The transfer risk disappears because nothing is sent to a third party. Your obligations under GDPR and similar rules still apply to how you store inputs and outputs, but you no longer have a processor relationship to audit for every prompt.
How long does it take to set up?
Installation takes about twenty minutes. Reaching a reliable workflow takes two to four weeks, because the work is building an eval set and measuring edit rates, not installing software.